Choosing an Industrial Alert Escalation System That Holds Up to Audit
An industrial alert escalation system decides who hears about a problem, how fast they hear it, and what happens when nobody responds. In a regulated plant, that decision carries weight beyond uptime. Every alert that fires, gets acknowledged, gets ignored, or gets handed up the chain is a record someone may later need to explain to an auditor. This guide is a selection framework for IT, quality, EHSQ, and operations leaders who need escalation behavior they can defend. It focuses on what the system does with an alert, what evidence it leaves behind, and how governance keeps it honest. This approach differs from focusing on which sensors connect to which gateways.
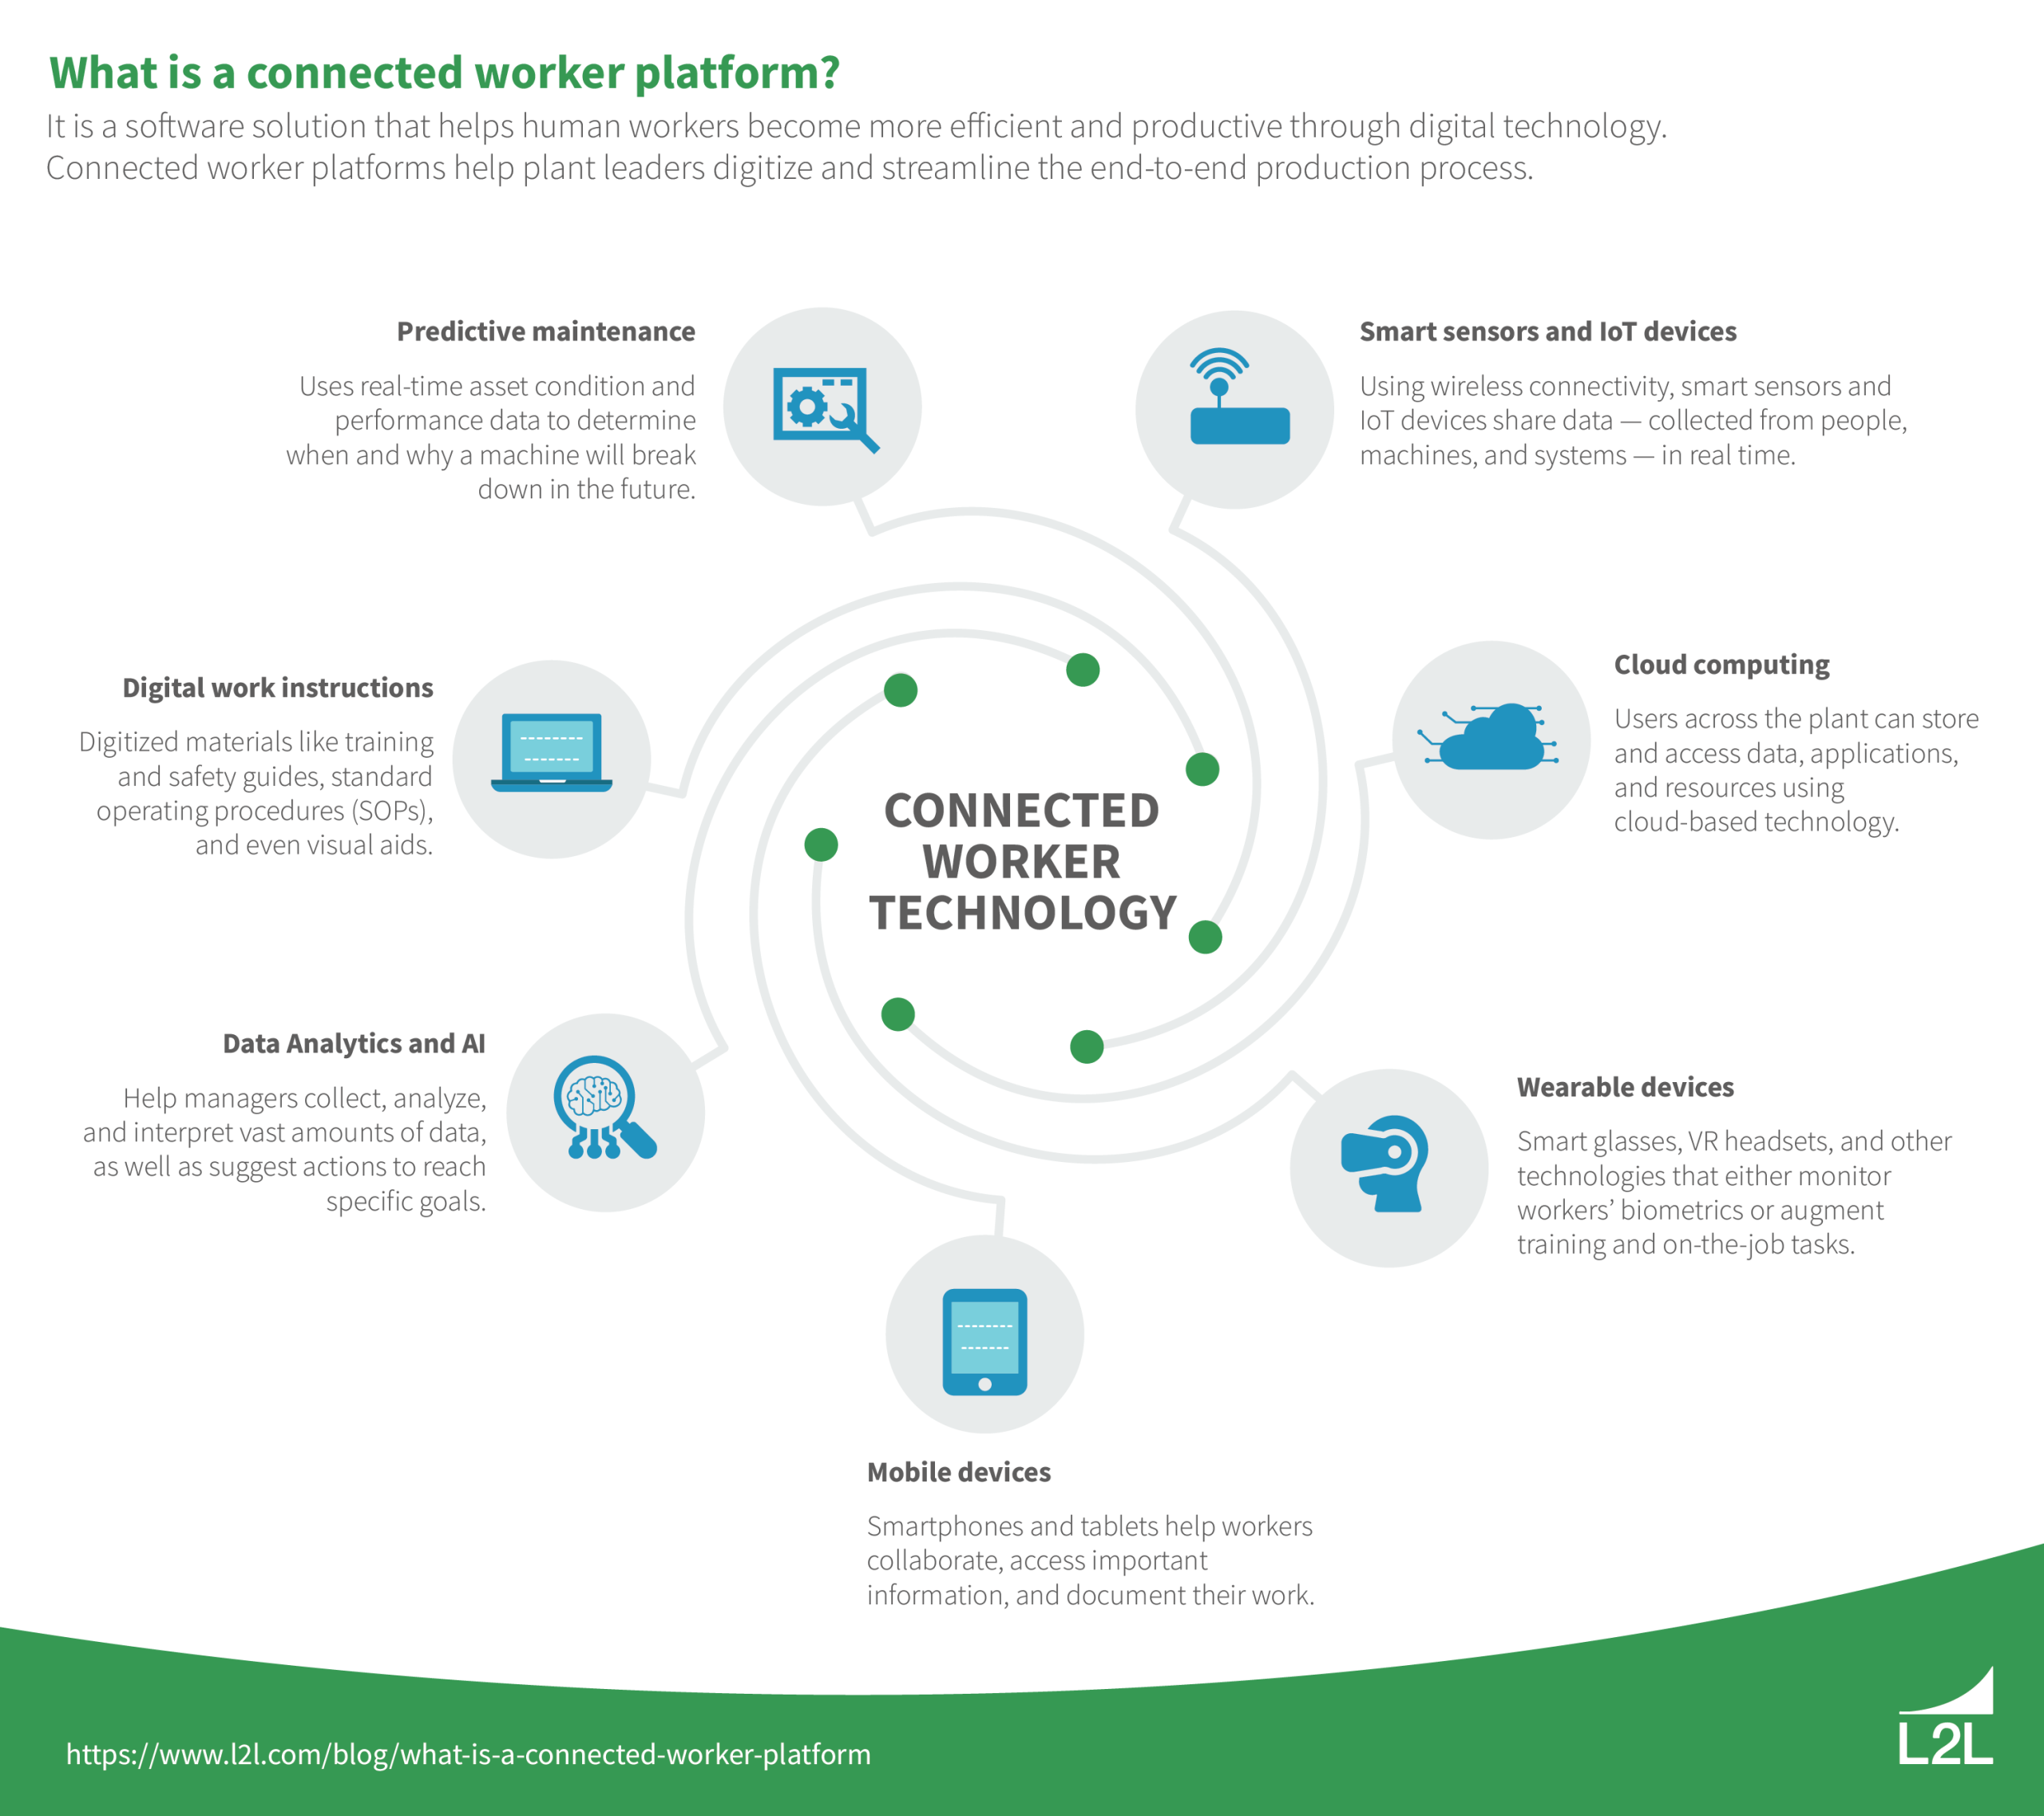
Escalation sits inside the broader connected operations category, which covers how frontline workers, assets, and procedures share data in real time. Connectivity gets most of the attention in vendor demos. Escalation logic is where regulated plants usually feel the pain. The rest of this article walks through the criteria to check, the questions to ask, and the verification steps. These steps separate a system that looks good on a slide from one that survives a shift handover and a validation review.
A short answer for the impatient: a strong industrial alert escalation system does four things reliably. It routes each alert to a defined role. It enforces time-based escalation when nobody acts, records every state change with an identity and a timestamp, and keeps that record intact. If a platform cannot prove those four behaviors during a trial, treat its marketing about faster response with caution.
What to Check in an Industrial Alert Escalation System Before You Commit
Most evaluations start with the wrong question. Teams ask whether the system can send an alert to a phone, and it almost always can. The better question is what the system must prove after the alert is sent. Start by writing down the outcomes you need. For a filling line, that might be an acknowledged response within a set window, a documented containment action, and a closed record linked to the batch. For a utility room, it might be a confirmed inspection and a signed exception. Those outcomes define the evidence you will later check.
Next, separate the alert from the response. An alert is a signal. The response is a human action, and the escalation system is the layer that connects the two and keeps a trail. Ask vendors to show that trail, not a dashboard summary. A useful demo has the vendor trigger a real alert on a test asset. The vendor then lets it go unacknowledged and shows the full sequence of events with timestamps. If the vendor cannot produce that sequence on demand, the feature may not exist in the form you need.
Finally, set your scoring criteria before the demo. Weight the items that protect compliance more heavily than convenience features. Governance, traceability, and offline behavior should carry more weight than a polished mobile layout. This keeps a persuasive presentation from pulling the scorecard away from the risks you actually carry.
Core Evaluation Criteria for Regulated Plants
Define escalation outcomes and evidence expectations (what proof is required and when)
Start by naming the outcome each alert type must reach and the proof that outcome requires. A temperature excursion on a cold-chain line may need an acknowledgment within minutes. It may also need a corrective action logged against the affected lot and a quality sign-off before release. A minor fault on a conveyor may only need a documented acknowledgment and a work order.
These are different evidence sets, and a single escalation rule applied to both will either bury critical events or flood the people who respond to them. Write the expectation for each alert class in plain language before you look at any software. Then ask each vendor how their system records the proof for each class and at what point the record becomes complete.
Pay attention to the word “when.” Some platforms log an acknowledgment but never capture the corrective step. The alert appears closed when the underlying issue is still open. Your evidence expectations should specify both the acknowledgment and the closure, along with the time between them. A system that cannot distinguish those two states is hard to defend during an inspection, because an auditor will ask what happened between them.
Governance design checks (roles, permissions, approval and exception handling)
Governance is where many escalation tools quietly fail regulated plants. The question is not only who receives an alert. It also covers who can change the rules that route alerts, who can silence them, and who can approve an exception. In a well-run plant, the operator on shift acknowledges and begins containment. The shift supervisor owns escalation after a set interval, and only quality or the responsible engineer can close a deviation.
A capable system lets you encode those roles and restrict permissions to match. Check whether escalation rules are versioned, and whether a change to a threshold or a routing path is itself logged with the user who made it. Ask how exceptions work. Sometimes a legitimate reason exists to pause escalation during a planned maintenance window, and that pause needs an approver, a reason, and an end time.
A system that lets anyone mute an alert without a trace will eventually produce a gap that nobody can explain. Test the permission model with a real scenario. Have a technician try to close a quality-owned alert and confirm the system refuses and records the attempt.
Data integrity requirements (timestamps, state transitions, identity, and tamper resistance)
Records need to be trustworthy, and that depends on four things: timestamps, state transitions, identity, and tamper resistance. Timestamps should come from a consistent time source across devices, and the system should show whether a time was recorded by the device or the server. A mismatch of several minutes between a machine controller and the escalation server can make a sequence of events look impossible. When weighing options, one field guide is a useful comparison point.
State transitions matter because an alert moves through stages such as raised, acknowledged, escalated, in progress, and closed. Each move should be a discrete, time-stamped event, not an overwritten status field. Identity means every action ties to a named, authenticated user or a defined system account, not a shared login at the kiosk. Tamper resistance is the piece people most often skip.
Ask whether previous records can be edited, and if so, whether edits leave an original copy and an audit entry. Regulated environments often reference the expectations in 21 CFR Part 11, the FDA rule on electronic records and signatures, when judging whether a system is trustworthy. You do not need to be a lawyer to ask the practical version: can someone alter the history of an alert without leaving a visible mark?
Integration and workflow alignment (how alerts link to SOP steps and corrective actions)
An alert that does not connect to the procedure meant to resolve it becomes a notification with no follow-through. Good escalation ties each alert type to the relevant standard operating procedure step and to the corrective action record. This makes the response visible in one thread. When an operator acknowledges a pressure alarm, the system should present the specific SOP step for that condition and capture completion of that step against the alert.
It should also open or link a corrective action when the condition is not cleared within the expected time. Ask vendors how they maintain these links when procedures change. If an SOP revision renames a step, do old alerts still point to the correct version of the instruction that was in force at the time? Integration with existing systems matters here too.
Many plants already run a maintenance management tool or a quality management system, and duplicating corrective action records in two places creates reconciliation work every month. Map a single real workflow from alarm to closure during the demo and count the manual handoffs. Each handoff is a place where the record can drift.
Operational reliability (offline/edge behavior, notification delivery, and latency)
An escalation system that depends on a single cloud connection will eventually fail at the worst moment. Plants have dead zones, network maintenance windows, and shielded areas where wireless signals struggle. Ask what happens when the connection drops. The better designs keep a local record at the edge, queue notifications, and then synchronize without losing the original timestamps once connectivity returns. Verify that the local queue survives a device restart.
Notification delivery deserves the same skepticism. Check which channels are supported, whether delivery is confirmed or only attempted, and what happens if a phone is off or a message is not read. A system that sends a push notification and treats silence as success will miss real events. Latency is the last measure.
Measure the time from a trigger at the machine to the alert appearing for the responsible role, under normal load and during a busy shift. Expect some delay, but know its size. A few seconds is usually acceptable for most line alarms. A safety-relevant signal may need a much tighter window and possibly a hardwired path that the software supplements rather than replaces.
Validation approach for deployment (how to test with real shifts and document results)
Validation proves that the system behaves as specified under the conditions it will actually face. Do not validate with a clean test script alone. Plan a trial that runs across real shifts, including the night crew, weekend coverage, and a changeover. Those are the periods when people are stretched and escalation is most likely to break. Write test cases before the trial begins.
Each case should state the trigger, the expected routing, the expected escalation time, the expected evidence, and the pass criteria. Include negative cases on purpose. These include an alert nobody acknowledges. They also cover a permission the user should not have, a network drop during an open event, and an attempt to edit a closed record. Record the actual results with timestamps and screenshots or exported logs, and keep them in your validation file.
Many quality teams follow a risk-based approach similar to the one described in general computer system validation guidance. They scale the depth of testing to the impact of each alert type. Be honest about limits. A trial of two weeks on one line will not reveal every failure mode. Schedule a review after the first full month and check the ignored-alert log against what you expected.
Finally, document any configuration you changed during the trial. An undocumented tweak made during testing is one of the most common reasons a validated system later fails review.
Operating Cost by Tier: What Usually Changes
Pricing varies widely between vendors, and published figures are often tied to user counts, sites, or modules. Rather than chase a specific number, it helps to understand what tends to change as you move up the tiers. The table below describes typical cost drivers, not quoted prices.
| Tier | Typically Included | What Usually Drives Cost |
|---|---|---|
| Entry | Limited alert sources, basic event logs, single-site use, standard notifications | Number of alert sources and users, basic log retention period |
| Mid | Role-based escalation rules, richer evidence workflows, SOP linking, offline queueing | Configuration effort, number of roles and escalation paths, integration with maintenance or quality systems |
| Premium | Multi-site governance, advanced validation support, integration services, extended audit retention | Site count, validation documentation scope, professional services for integration and testing |
The cost gap between tiers often reflects the work of making an industrial alert escalation system defensible rather than the software license alone. Ask each vendor to itemize what a validation package includes and who performs the integration work. A low headline price can hide a large bill for configuration and testing.
Verification Checklist for Vendor Demos and Final Selection
Before you sign, take a short checklist into every demo. Confirm that the system defines clear lifecycle states for each alert and that every transition is timestamped with a named user. Ask to see an ignored-alert log, and check that it shows escalations that fired automatically when no one responded. Test escalation routing with a real role change, and verify that the new path takes effect without a software release. Finally, trace one alert from trigger to closed evidence, and confirm the corrective action, SOP step, and approval all link back to the same record.
A good escalation system is not the one with the most features. It is the one whose behavior you can explain to an auditor on a bad day. If you want a practical view of how these decisions play out on a plant floor, consider this. One field guide on quality control in manufacturing is worth a look alongside your own process mapping. Start with the four behaviors named at the top of this article. Test them on real shifts, and let the records tell you whether the system is ready.
Frequently Asked Questions
How is an alert different from an escalation?
An alert is the signal that something needs attention, such as a temperature reading outside its limit or a fault code from a machine. An escalation is what happens when that signal is not handled within a defined time. The system moves the alert to a higher role, notifies a backup contact, or opens a formal deviation. Good systems treat both as recorded events, so you can see the original trigger, each attempt to notify, and the point at which a person took ownership.
Does every alert need to escalate?
No, and forcing every alert into an escalation path is a common mistake. Escalation works best when reserved for conditions that carry real risk to quality, safety, or compliance. Minor, routine alerts often need only an acknowledgment and a logged note. Sort alerts into a small number of classes during your evaluation, then assign escalation rules to each class. This keeps supervisors from being flooded and makes the critical events easier to spot in the log.
What should an auditor be able to see in the record?
An auditor should be able to follow one alert from trigger to closure without relying on memory or side spreadsheets. That means the original timestamp, every state change, the named user behind each action, any escalation that fired and when. It also includes the SOP step or corrective action linked to the event and the approval for closure. If a record was edited after the fact, the original value and the edit entry should both be visible. Test this by pulling a real record during the demo.
Can an escalation system work if the network goes down?
It depends on the design. Some platforms queue events locally at the edge and synchronize them once the connection returns, keeping the original timestamps intact. Others simply stop recording until the link is restored, which leaves a gap in the record. Ask the vendor to demonstrate a deliberate network interruption during the trial and check whether events raised during the outage appear afterward in the correct order. This single test reveals more about reliability than most feature lists do.
How long should a validation trial run?
Plan for a trial that covers real shifts rather than a single day of scripted tests. Many teams run a pilot across several weeks and include at least one changeover, a weekend, and a night shift. Those periods put the most pressure on escalation. The exact length depends on how often your critical alerts occur. The aim is to generate enough real events to test every escalation path, and to review the ignored-alert log against your expectations before deciding.
Who should own escalation rules after go-live?
Ownership should sit with a named role in quality or operations, not with whoever happens to have administrator access in the software. That owner approves changes to routing, thresholds, and exception rules, and the system should log each change with the user and the reason. Shared ownership between IT and the operating team usually works best, with IT maintaining the platform and the business owner controlling the rules. Review the rule set on a regular schedule and after any significant process change.
About this guide
This guide is written from a general industry perspective on selecting escalation tools for regulated manufacturing. It draws on common validation and governance practice rather than on any single vendor’s product or a specific plant’s results.
Related subtopics
- Connected worker platform governance for regulated plants
- Alarm rationalization and alert classification
- Electronic records and audit trails in manufacturing
- Validating digital work instructions on the shop floor
- Offline-capable frontline operations software
Further Reading
- Choosing an escalation system for regulated plants: governance, logging, and validation checks
- Industrial alert escalation system selection: a criteria framework for compliance and uptime
- Regulated manufacturing platform choice for alert escalation: what to verify
Related Posts
Which connected worker platform fits your manufacturing stack: integration, security, and rollout
What Is Connected Worker Platform? What Is Connected Worker Platform?…
Adopting connected worker solution for unionized workforces
Connected worker platform rollout change management for unionized frontline workforces…
corvex connected worker integrations guide to real-world IT fit
Common Integration Failures in Connected Worker Rollouts Common Integration Failures…