Ignored downtime alerts are one of the most frustrating problems on a plant floor. The alert fires. The light flashes. The horn sounds. Somehow the line keeps running in a degraded state for another forty minutes. Most of the time, the operator isn’t being careless or lazy. The industrial alert escalation system around them simply doesn’t fit the way a busy shift actually works. This article walks through why operators ignore downtime alerts during busy shifts. It shows how to troubleshoot the escalation design. Alerts then lead to action instead of noise. If you have ever stood on a line during a bad afternoon, you already know the problem. You watched a supervisor walk past a flashing tower light without a second glance. The question is what to change, and in what order.
The industrial alert escalation system sits inside the wider field of connected operations. Machine signals, work instructions, and frontline people are linked together. Within that field, escalation is the part that decides who hears about a problem. It decides how long they have to respond. It also decides what happens when nobody does. It is easy to think of alerts as the visible part of the system. Escalation is the logic underneath. It determines whether an alert is a useful interruption or just another sound in the background. A well-designed escalation path quietly does a lot of work. It filters, routes, times, and records every event. The right person gets the right message at the right moment.
Why Operators Ignore Downtime Alerts During Busy Shifts
Here’s the short answer. Operators ignore downtime alerts when the alert is frequent, vague, or impossible to act on in the time they have. That’s a design problem, not a willpower problem. When a press operator is managing three changeovers, a material shortage, and a quality hold, another amber light becomes background noise. The alert itself may be correct. The system around it has taught people that most alerts don’t need them right now. Over weeks and months, this lesson gets reinforced every time an alert clears on its own. It gets reinforced every time a supervisor says “that one always resets.” It also gets reinforced every time a genuine problem turns out to be a sensor drifting out of calibration. Operators are responding rationally to the signals they have been given.
Shift pressure makes this worse. Peak workload windows, such as the first hour after a handover or the middle of a high-volume run, are exactly when alerts multiply. Attention shrinks at those times. A changeover on one line often coincides with a slow feed on another. A minor jam can trigger a chain of downstream warnings. All of them look equally urgent. Unclear next steps add another layer.
If the alert says “Line 4 speed low” and nothing else, the operator has to diagnose the problem. They must decide whether it’s worth stopping for. Most operators will wait. They hope it clears on its own. Sometimes it does. That reinforces the habit.
In a plant I have worked with, the single most common response to a speed-low alert was to tap acknowledge and go back to the task in hand. This happened not because anyone wanted to lose output. It happened because the alert gave no clue about whether the problem was a jam, a bad batch, or a drive fault.
The fix starts with treating the alert as part of the industrial alert escalation system. It is not a standalone warning. The eight-step flow below gives you a way to check each part of that process. The flow covers timing and severity. It also covers the escalation path and a live test on the floor. Each step is designed to answer one specific question. Most plants find that the answers to the first three or four explain the majority of ignored alerts. You do not need a consultant or a new platform to start. You need the alert history, a stopwatch, a few conversations with operators, and the willingness to admit that the design may be the thing that needs changing.
Troubleshooting Escalation Design Step by Step
Work through these steps in order on one line or one alert type first. You’ll usually find that two or three of them explain most of the ignored alerts in the industrial alert escalation system. Don’t try to redesign everything at once. A focused investigation on a single line will give you cleaner evidence. It gives faster feedback. It also leads to far fewer arguments about which change caused which result.
-
Industrial Alert Escalation System
Confirm alert timing against shift peak workload windows
Pull the timestamps of every downtime alert for the last four to six weeks. Group them by hour and by shift. Lay them against the production schedule, changeover times, and handover periods. In most plants, you’ll see a cluster of alerts landing in the same windows where operators are already stretched. If the highest alert volume falls during the first thirty minutes of a shift or during a known changeover, the problem is timing, not attention. The practical fix is to suppress non-critical alerts during those windows. Or route them to a supervisor instead of the operator at the machine. It also helps to ask the outgoing shift which alerts they remember as “always going off at handover.” Those informal answers often point you to a pattern the logs alone would hide.
-
Check alert relevance and severity scoring
Count how many alerts were acknowledged without any action taken. If the number is high, the alert is probably too noisy. Look at the severity assigned to each alert type. Ask whether a stop-the-line condition is really tagged as critical while a cosmetic drift is tagged the same way. Many systems inherit default severity levels from the controller. They never get reviewed. A useful test is to ask operators which alerts they would stop for right now. Then compare their answers with the severity labels. Where the two disagree, the scoring needs adjusting. The goal is a short list of alerts that reliably mean something. A good rule of thumb is that if more than a fifth of your critical alerts are cleared without any recorded action, the critical tier has been inflated. It needs to be pared back.
-
Verify the next action an operator can take in two to five minutes
For each alert, write down the first physical action an operator can take. Also note how long it realistically takes. “Check the infeed sensor and clear any jam” is a good next action. “Investigate root cause of low throughput” is not. Nobody can do that in five minutes at the machine. If an alert has no defined action that fits inside that window, it will almost always be ignored or deferred. The operational side is something Vardian why are operators ignoring downtime alerts during busy shifts? expands on with real numbers. This pairs well with What an industrial alert escalation system needs to do to prevent…, which works through concrete examples.
Add the action to the alert message itself. Link it to the relevant work instruction so the operator doesn’t have to search for it. Keep the instruction short enough to read at a glance. Walk the line yourself with a clipboard. Time each action honestly.
You will often discover that the documented fix takes twelve minutes. A guard must be opened. A tool must be fetched from the crib. A lockout must be applied. That information changes how the alert should be framed.
-
Validate acknowledgement requirements
Define what counts as “seen.” In many systems, a single button press clears the alert. Nothing was done. That teaches people to acknowledge reflexively. Decide whether acknowledgement should require a reason code. It could require a confirmation that the action was started. Or it could require a status update. Then define what triggers escalation. It could be a missing acknowledgement after a set time. Or it could be an acknowledgement without a status change after a set time. Be careful about asking for too much. A reason code is useful. A paragraph of notes during a jam is not. It will push people toward skipping the acknowledgement entirely. A short pick-list of six or seven common causes, plus an “other” option that prompts a quick free-text word, usually strikes the right balance. It gives the supervisor enough data to spot recurring faults later.
-
Audit escalation thresholds
Escalation timers are where most designs break. If the threshold is too long, say thirty minutes before a supervisor hears about a stopped line, operators learn that waiting is safe. The alert quietly becomes a loss of output. If the threshold is too short, say two minutes, supervisors get flooded. They start ignoring the escalations. Operators feel pressure to panic-call for every small event. Check the actual downtime durations for each alert type. Compare them with the escalation timers. A threshold should sit just above the typical self-recovery time. It should sit well below the point where the loss becomes expensive. You’ll usually need different thresholds for different severities. Do not use one value for everything. For example, a feeder blockage that clears in ninety seconds in most cases might warrant a four-minute operator window before escalation. A hydraulic pressure fault that never self-recovers might escalate almost immediately to maintenance.
-
Review escalation recipients and their access
An escalation that lands on someone who can’t act on it is the same as no escalation. Check who receives each alert at each level. Check whether that person has the permissions to restart equipment. Check whether they can approve a deviation. Check whether they can call maintenance. Also check presence. If the escalation goes to a maintenance lead who is off site on a rotating schedule, the message will sit unread. Map the recipients against the actual shift roster. Include nights, weekends, and holidays. Many plants find that the backup contact on paper hasn’t worked a shift in months. Fixing this often means adding a clear secondary and tertiary recipient. Confirm each one can actually log in and respond. It is also worth checking mobile notification settings. An alert that goes to a desktop inbox in an office is invisible to someone standing on the floor with gloves on.
-
Measure resolution latency by severity and shift
Resolution latency is the time between the alert firing and the situation being cleared. Measure it separately for each severity level and each shift. Do not measure it as one average. A plant average can look healthy while nights take three times as long to respond to the same alert type. Compare latency with the number of escalations. Compare it with the presence of a supervisor on the floor. You’re looking for patterns that point to a specific shift, a specific crew, or a specific alert type. Those patterns tell you where the next round of changes should go. They give you a baseline to measure against after the redesign. Keep the baseline honest by using the same definitions before and after. If you change what “cleared” means in the middle of the project, the comparison becomes meaningless.
-
Run a controlled test with the real SOP steps
Before rolling anything out widely, test the revised design on a single line and a single shift pattern. Use the actual standard operating procedure steps. Do not use a simplified demo version. Observe whether operators follow the intended path. Do they see the alert? Do they read the next action? Do they acknowledge with the right reason? Do they hit the correct escalation if needed? Note every point where people hesitate or improvise. Those hesitations usually show a gap in the instruction, the permissions, or the wording of the alert. Be honest about what you see. A test that only confirms the design is not much of a test. Invite a skeptical operator to be part of the trial. Their objections will reveal problems that a manager reviewing the design on a screen will never notice.
Common Escalation Mistakes and What to Do Instead
Certain patterns show up in almost every plant that struggles with ignored alerts. Recognizing them early saves a lot of wasted effort. It helps to name them explicitly when you discuss changes with the team.
-
❌ Wrong: adding more alerts to catch problems that the current alerts already miss.
✅ Right: improving triage on the alerts you already have, so the important ones stand out. -
❌ Wrong: escalating to a role that has no permission to act on the problem.
✅ Right: mapping each escalation level to someone who can restart, approve, or call for help. -
❌ Wrong: requiring detailed manual evidence from operators during a peak window.
✅ Right: using a short reason code and letting the supervisor collect detail after the event. -
❌ Wrong: using one escalation timer for every alert type across every shift.
✅ Right: setting thresholds from real downtime patterns, with separate values for severity and shift.
Redesigning Escalation for Shift Reality
Once you’ve worked through the steps for the industrial alert escalation system, the redesign tends to follow naturally. Keep the alert list short. Give each alert a real next action. Make acknowledgement meaningful. Send escalations to people who are present and able to respond. Thresholds should reflect how long problems actually last. They should not reflect how long someone hopes they will. None of this requires new hardware. It requires looking closely at how the existing alerts behave during the busiest hours of a shift. In practice, the biggest gains usually come from removing alerts rather than adding them. Plants that cut a list of forty downtime messages down to twelve, each with a clear owner and a clear action, often see acknowledgement quality improve within the first week.
Start small. Choose one shift pattern and one alert type. Run the revised design for a few weeks. Compare latency and acknowledgement quality with the baseline. If the numbers improve and operators say the alerts make sense, extend the design to the next line. If they don’t, you’ll know exactly which step needs another look. Share the results openly with the shift crews. Include the setbacks. Operators are far more willing to trust a redesign when they can see the reasoning behind each change. They know that their feedback actually shaped the outcome.
Validating Your Revised Escalation Plan Before Wider Rollout
Ignored downtime alerts are almost always a sign that the industrial alert escalation system no longer matches the work on the floor. The fix is methodical rather than dramatic. Check timing, severity, next actions, acknowledgement, thresholds, recipients, and latency. Then test the result with real procedures. Pick one shift pattern and one alert type. Validate the changes there. Only then widen the scope. That approach keeps the risk low. It gives you evidence you can show to the people who have to live with the alerts every day. Once the pilot holds up, document the final design, the thresholds, and the reasons behind them. The next team to inherit the system understands why it works the way it does.
Frequently Asked Questions
Why are operators ignoring downtime alerts during busy shifts?
Usually because the alerts arrive too often. They carry too little information. Or they require more time to act on than the operator has available during a peak period. Repeated false alarms and alerts that clear on their own teach people that waiting is safe. The alert gradually loses meaning.
How do I know if my alert volume is too high?
Look at how many alerts are acknowledged with no recorded action. Look at how many clear without intervention. If a large share of your alerts fall into those categories, the list is probably too noisy. It needs pruning or better severity scoring.
What is a good escalation timer for downtime alerts?
There is no universal number. A good starting point is to compare the typical self-recovery time for each alert type with the cost of lost output. The threshold should sit just above the usual self-recovery time. It should differ by severity and by shift rather than using one value everywhere.
Should operators have to enter detailed notes when they acknowledge an alert?
Generally no, at least not during the event itself. A short reason code from a pick-list is more practical. Detailed notes can be collected by the supervisor after the situation is resolved. The operator has time to reflect and write properly.
Who should receive escalations when the primary contact is unavailable?
Define a clear secondary and tertiary recipient for each alert type and shift. Confirm that each person has the access rights to act and the mobile notifications set up. Check the backup roster regularly. Paper plans often drift away from who is actually working.
How long should I test a revised escalation design before rolling it out?
Most pilots run for three to six weeks on one line and one shift pattern. That is long enough to capture a range of conditions. Include at least one peak period and one quieter stretch. Compare latency and acknowledgement quality against your baseline before deciding whether to expand.
Further Reading
- How to choose an industrial alert escalation system for regulated manufacturing
- What happens if someone ignores a real-time alert: logging, escalation, and proof
- What an industrial alert escalation system needs to do to prevent silent failures
- How does connected worker inspection software work when connectivity drops during a shift?
- What to look for in connected worker inspection software for manufacturing plants
Related Posts
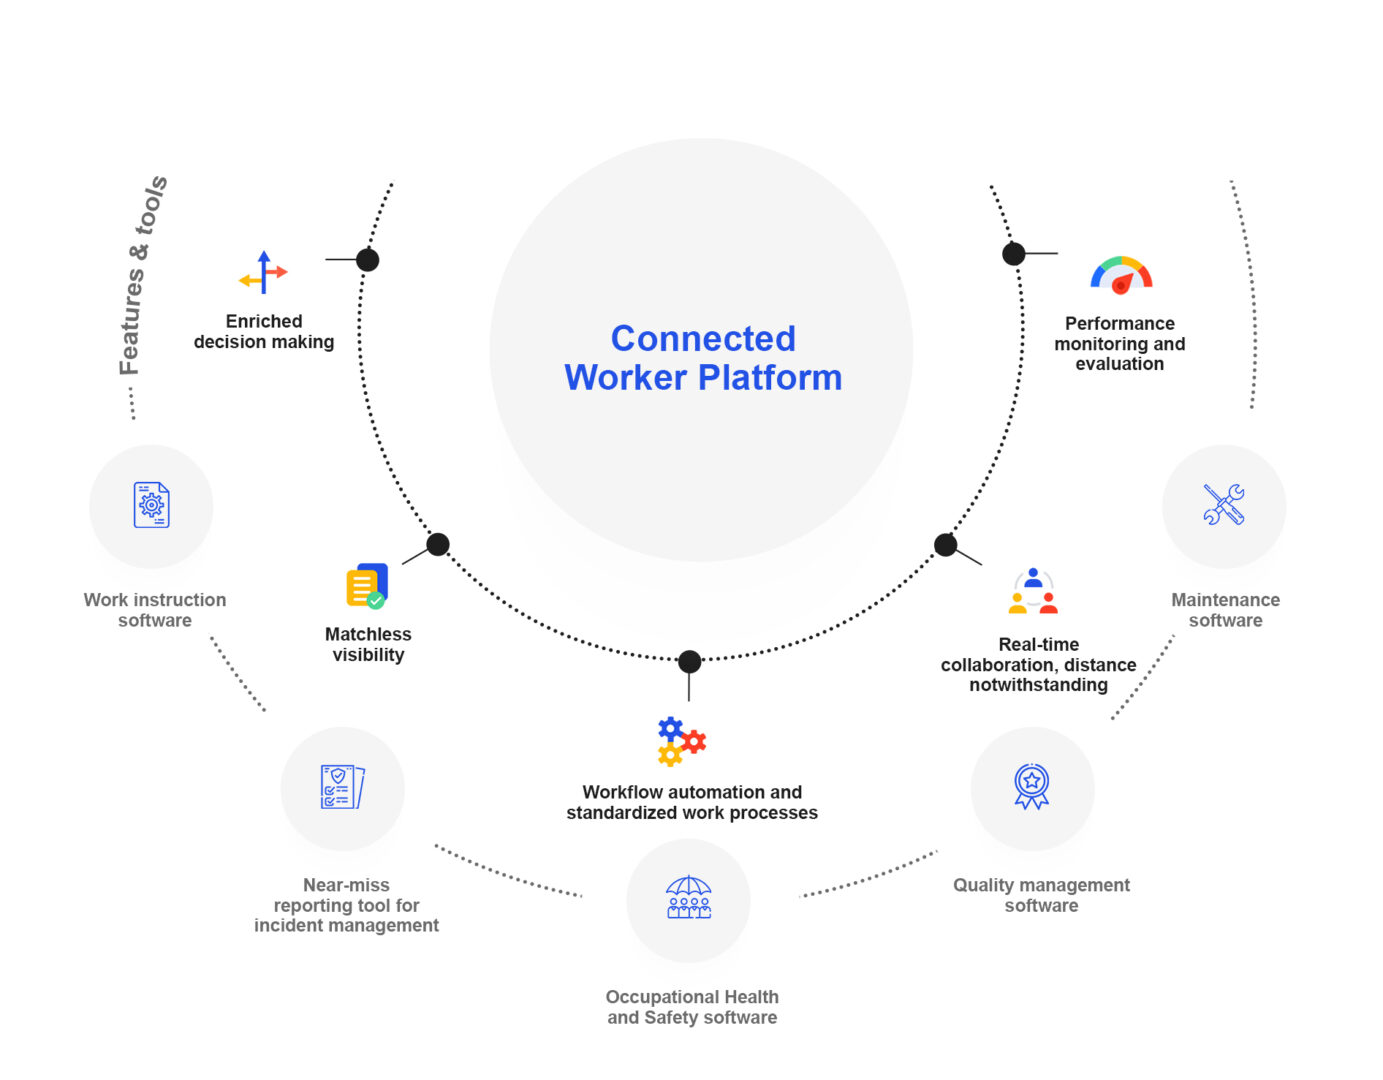
Which connected worker platform fits manufacturing teams: a feature and vendor reality check
Manufacturing platform success criteria Manufacturing teams measure success for any…
Governance checklist using connected worker platform audit trail features
Governance checklist for regulated manufacturing plants using a connected worker…
Connected Frontline Worker Pricing in UK for 2026: Cost Drivers
The Challenge of Pricing Connected Frontline Worker Deployments The Challenge…